Inside the Cognitive Substrate: How Next-Generation AI Systems Are Evolving Beyond Statistical Learning
Author(s): Zain Ahmad Originally published on Towards AI. Sharing my journey through the next frontier of AI development and cognition I still remember the first time I really paused and thought about what AI could do beyond just predicting the next word …
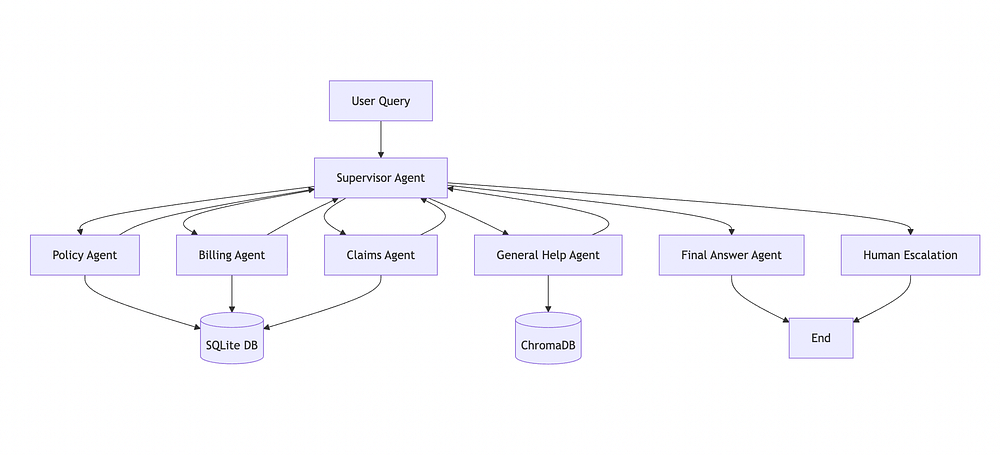
Agentic AI Project: Build a Multi-Agent System With LangGraph
Author(s): Alpha Iterations Originally published on Towards AI. This is an end-to-end project on building a multi-agent insurance support system using Agentic AI [LangGraph and OpenAI API]. [Code Included]. Non members read here for free. Multi Agent System Architecture [Image by Author]The …
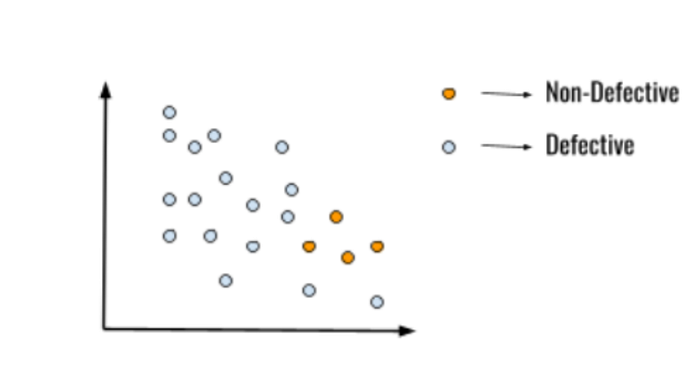
How to Handle an Imbalanced Dataset In Machine Learning Using SMOTE
Author(s): Tanesh balodi Originally published on Towards AI. How to Handle an Imbalanced Dataset In Machine Learning Using SMOTE All that people ask for in a machine learning model is the accuracy of the model; this accuracy is sometimes nothing but a …
RAG: The Backbone of Modern AI Applications — What, Why, How, and the Latest Advancements
Author(s): Yuval Mehta Originally published on Towards AI. Photo by Kevin Ku on Unsplash Artificial Intelligence has reached a stage where models can generate fluent, human-like text, but not always factually correct or context-aware. This is where Retrieval-Augmented Generation (RAG) comes into …

The Tools That Automate 90% of Your Work While You Get a Good Night’s Sleep
Author(s): Shreyansh Jain Originally published on Towards AI. A practical breakdown of how deep agents like Gemini, ChatGPT, and Claude plan, read, and research for you — even overnight. To understand why tools like Gemini Deep Research feel so powerful, we need …
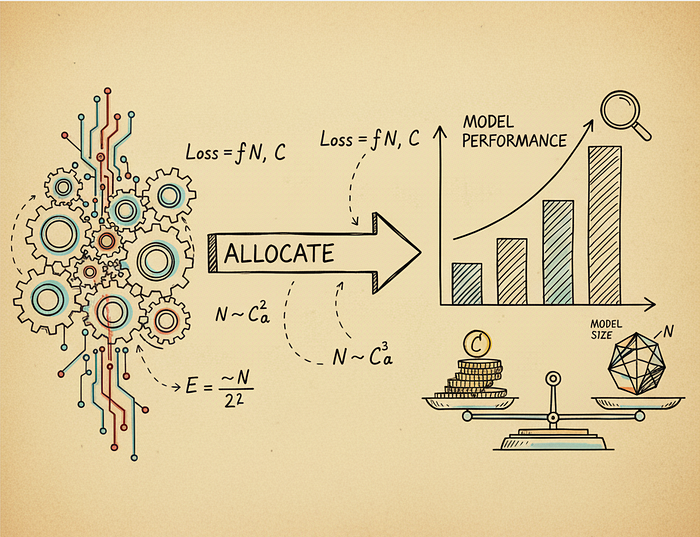
Scaling Laws: How to Allocate Compute for Training Language Models
Author(s): M Originally published on Towards AI. From Chinchilla’s 20:1 rule to SmolLM3’s 3,700:1 ratio: how inference economics rewrote the training playbook Training a language model is expensive. Really expensive. A single training run for a 70 billion parameter model can cost …

Cookiecutter Data Science: A Standardized, Flexible Approach for Modern Data Projects
Author(s): Abinaya Subramaniam Originally published on Towards AI. In the ever-evolving world of data science, one of the biggest challenges isn’t the algorithms or tools, it’s project organization. If you are working solo or collaborating with a team, maintaining a clean, reproducible, …
Transformer in Action —Optimizing Self-Attention with Attention Approximation
Author(s): Kuriko Iwai Originally published on Towards AI. Discover self-attention mechanisms and attention approximation techniques with practical examples The Transformer architecture, introduced in the “Attention Is All You Need” paper, has revolutionized Natural Language Processing (NLP). Photo by NordWood Themes on UnsplashThis …

Data Lakes in Enterprises
Author(s): Flora Nanda Originally published on Towards AI. Data is now widely seen as the new “gold standard” in the AI revolution. In the context of AI, data is the critical foundation and enabler for everything from model training to real-time decision-making …
It Looks Like GPT-5.1 Leaked – Polaris Alpha
Author(s): Mandar Karhade, MD. PhD. Originally published on Towards AI. Good for coding front-end, a bit slow, new release from OpenAI The AI community is trying to piece together a new wave of discoveries that all seem to point straight at the …

Why Missing Data Is Not Missing at Random and Why That Matters
Author(s): ANGELI WICKRAMA ARACHCHI Originally published on Towards AI. The medical study that got it wrong You’re analyzing a clinical trial for a new antidepressant: 1,000 patients enrolled 700 completed the 3-month follow-up 300 patients have missing follow-up scores Your team says: …
From raw text to training gold: How to collect and prepare data for custom LLMs
Author(s): Laura Verghote Originally published on Towards AI. Practical guidance for building clean, domain-relevant datasets for fine-tuning, continued pretraining, or training from scratch If you’ve worked on language models beyond a quick prototype, you already know where the real bottleneck is. It’s …
Data Quality and Filtering at Scale for Training Large Language Models
Author(s): M Originally published on Towards AI. From heuristic filters to AI classifiers: practical techniques for curating trillion-token datasets Training a language model on the raw internet is like trying to learn from every conversation happening in the world simultaneously. Most of …

Sourcing and Collecting Data for Training Large Language Models
Author(s): M Originally published on Towards AI. Real-world insights from FineWeb, DCLM, The Stack v2, and modern LLM training When people talk about training language models, the conversation often jumps straight to architecture choices or training techniques. But here’s the reality: you …

The End of Prompt Engineering? Stanford’s Self-Improving AI Learned Clinical Reasoning on Its Own
Author(s): Marie Humbert-Droz, PhD Originally published on Towards AI. Stanford’s Agentic Context Engineering lets models reflect, learn, and build their own playbook. I tested it on clinical lab data — and watched it teach itself temporal reasoning. As we saw in my …
Recent Posts